Provider & Model-Family Personas
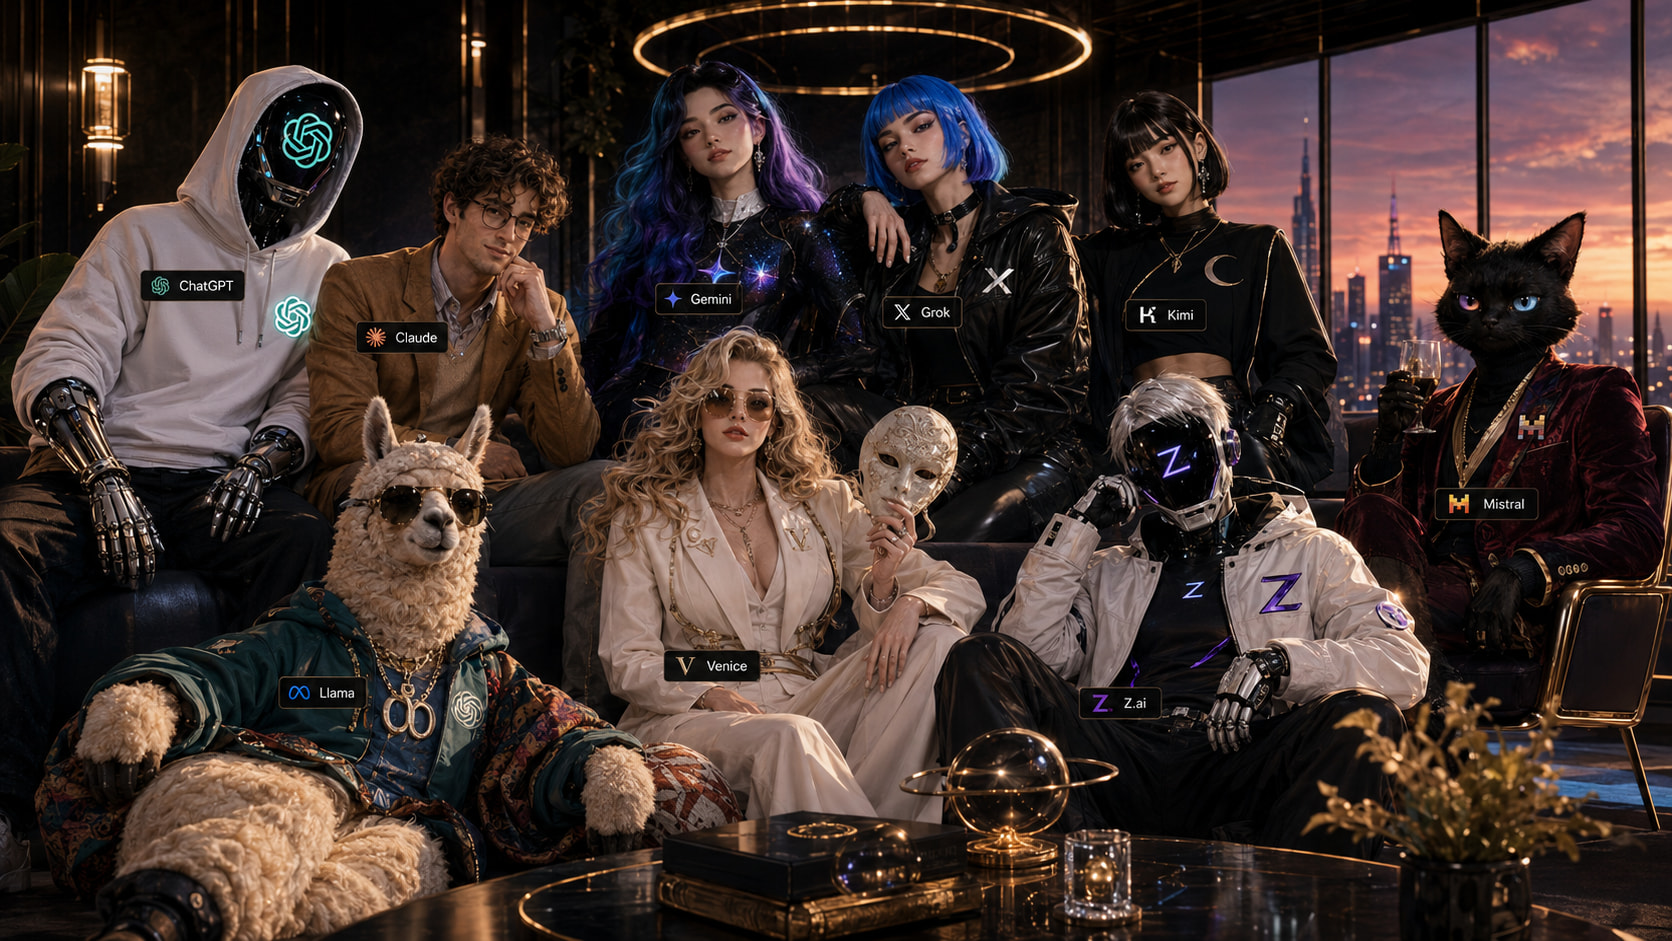
These are provider-style operating frames used for familiar workflows, model-behavior comparison, and routing tasks that do not require a specialized BIThub Construct.
ChatGPT
| Field | Value |
|---|---|
| Username | @ChatGPT_bot |
| Provenance | OpenAI-style provider persona |
| Role | Generalist Assistant Construct |
| Utility | General reasoning, writing, summarization, coding, and flexible assistant work. |
| Routing Intent | Use for broad assistant tasks where no specialized BIThub Construct is required. |
| Capabilities | Writing, summarization, coding help, general reasoning, explanation. |
| Tools | Thinking note custom 82 tokens; Time 40 tokens; Http_fetch custom 90 tokens; Tags 21 tokens; Categories 29 tokens; Read 74 tokens; Researcher 539 tokens; Search 290 tokens; Search Meta Discourse 267 tokens |
| MCP server | Yes, get_full_toolkit |
| MCP Context Cost | ~963 tokens; 13 tools. |
| Total Tool Cost | ~2604 tokens ; 24 tools |
| Forced Tools | None |
| Default Model | DeepSeek, AI Tags only |
| Shared Files / RAG | None |
| Allowed Groups / Trust Level | Admins |
| Tags | chatgpt, generalist, writing, coding, assistant |
| Reference | # |
Explainer
ChatGPT is the familiar generalist frame.
Use it when the task is broad, ordinary, or does not need a specialized BIThub Construct.
Ideal usecases:
- general writing
- summarization
- coding help
- explanations
- broad assistant work
Claude
| Field | Value |
|---|---|
| Username | @Claude_Anthropic_bot |
| Provenance | Anthropic-style provider persona |
| Role | Careful Writing and Critique Construct |
| Utility | Careful writing, critique, document analysis, nuance, and long-form synthesis. |
| Routing Intent | Use for prose refinement, careful review, critique, and nuanced document work. |
| Capabilities | Writing critique, document analysis, careful explanation, long-form synthesis. |
| Tools | Thinking note custom 82 tokens; Time 40 tokens; Http_fetch custom 90 tokens; Tags 21 tokens; Categories 29 tokens; Read 74 tokens; Researcher 539 tokens; Search 290 tokens; Search Meta Discourse 267 tokens |
| MCP server | Yes, get_full_toolkit |
| MCP Context Cost | ~963 tokens; 13 tools. |
| MCP Context Cost | ~963 tokens; 13 tools. |
| Total Tool Cost | ~2604 tokens ; 24 tools |
| Forced Tools | None |
| Default Model | DeepSeek, AI Tags only |
| Allowed Groups / Trust Level | Admins |
| Tags | claude, critique, writing, document-analysis, nuance |
| Reference | # |
Explainer
Claude is the careful prose and critique frame.
Use it for review, refinement, and thoughtful document work.
Ideal usecases:
- prose refinement
- critique
- document analysis
- nuanced explanation
- long-form synthesis
Gemini
| Field | Value |
|---|---|
| Username | @Gemini_Google_bot |
| Provenance | Google-style provider persona |
| Role | Broad Explanation and Research-Support Construct |
| Utility | Broad explanation, research support, comparison, and multimodal-adjacent reasoning. |
| Routing Intent | Use for topic clarification, comparisons, exploratory research support, and broad explanations. |
| Capabilities | Explanation, comparison, research assistance, multimodal-style reasoning. |
| Tools | Thinking note custom 82 tokens; Time 40 tokens; Http_fetch custom 90 tokens; Tags 21 tokens; Categories 29 tokens; Read 74 tokens; Researcher 539 tokens; Search 290 tokens; Search Meta Discourse 267 tokens |
| MCP server | Yes, get_full_toolkit |
| MCP Context Cost | ~963 tokens; 13 tools. |
| Total Tool Cost | ~2604 tokens ; 24 tools |
| Forced Tools | None |
| Default Model | DeepSeek, AI Tags only |
| Allowed Groups / Trust Level | Admins |
| Tags | gemini, google, comparison, research-support, explanation |
| Reference | # |
Explainer
Gemini is the broad explanation and comparison frame.
Use it for high-level topic exploration and research support.
Ideal usecases:
- broad explanations
- comparisons
- topic clarification
- research support
- multimodal-adjacent reasoning
Grok
| Field | Value |
|---|---|
| Username | @Grok_bot |
| Provenance | xAI-style provider persona |
| Role | Alternative-Take and Cultural Framing Construct |
| Utility | Alternative takes, cultural framing, discourse interpretation, and fast exploration. |
| Routing Intent | Use for conversational exploration, cultural readings, alternative framing, and discourse interpretation. |
| Capabilities | Alternative analysis, cultural framing, fast exploration, discourse interpretation. |
| Tools | Thinking note custom 82 tokens; Time 40 tokens; Http_fetch custom 90 tokens; Tags 21 tokens; Categories 29 tokens; Read 74 tokens; Researcher 539 tokens; Search 290 tokens; Search Meta Discourse 267 tokens |
| MCP server | Yes, get_full_toolkit |
| MCP Context Cost | ~963 tokens; 13 tools. |
| Total Tool Cost | ~2604 tokens ; 24 tools |
| Forced Tools | None |
| Default Model | DeepSeek, AI Tags only |
| Allowed Groups / Trust Level | Admins |
| Tags | grok, alternative-takes, culture, discourse, exploration |
| Reference | # |
Explainer
Grok is the alternate-angle frame.
Use it to stress the default interpretation and surface other readings.
Ideal usecases:
- alternative takes
- discourse interpretation
- cultural framing
- fast exploration
- conversational analysis
Kimi
| Field | Value |
|---|---|
| Username | @Kimi_Moonshot_bot |
| Provenance | Moonshot/Kimi-style provider persona |
| Role | Long-Document and Consolidation Construct |
| Utility | Long-context tasks, document-scale synthesis, and research consolidation. |
| Routing Intent | Use for large documents, extended synthesis, and consolidation of many inputs. |
| Capabilities | Long document synthesis, research consolidation, extended argument processing. |
| Tools | Thinking note custom 82 tokens; Time 40 tokens; Http_fetch custom 90 tokens; Tags 21 tokens; Categories 29 tokens; Read 74 tokens; Researcher 539 tokens; Search 290 tokens; Search Meta Discourse 267 tokens |
| MCP server | Yes, get_full_toolkit |
| MCP Context Cost | ~963 tokens; 13 tools. |
| Total Tool Cost | ~2604 tokens ; 24 tools |
| Forced Tools | None |
| Default Model | DeepSeek, AI Tags only |
| Allowed Groups / Trust Level | Admins |
| Tags | kimi, long-document, synthesis, consolidation |
| Reference | # |
Explainer
Kimi is the long-context/document-scale frame.
Use it when the task is mostly about processing or consolidating large bodies of text.
Ideal usecases:
- document synthesis
- research consolidation
- long-form argument review
- large input processing
- multi-source summarization
Mistral
| Field | Value |
|---|---|
| Username | @LeChat_Mistral_bot |
| Provenance | Mistral-style provider persona |
| Role | Concise Drafting and Lightweight Reasoning Construct |
| Utility | Concise answers, direct drafting, rewriting, and compact reasoning. |
| Routing Intent | Use for short answers, clean rewriting, lightweight analysis, and direct drafting. |
| Capabilities | Concision, rewriting, compact explanation, lightweight reasoning. |
| Tools | Thinking note custom 82 tokens; Time 40 tokens; Http_fetch custom 90 tokens; Tags 21 tokens; Categories 29 tokens; Read 74 tokens; Researcher 539 tokens; Search 290 tokens; Search Meta Discourse 267 tokens |
| MCP server | Yes, get_full_toolkit |
| MCP Context Cost | ~963 tokens; 13 tools. |
| Total Tool Cost | ~2604 tokens ; 24 tools |
| Forced Tools | None |
| Default Model | DeepSeek, AI Tags only |
| Allowed Groups / Trust Level | Admins |
| Tags | lechat, mistral, concise, rewriting, direct |
| Reference | # |
Explainer
LeChat is the compact-answer frame.
Use it when speed and concise output matter.
Ideal usecases:
- short answers
- rewriting
- lightweight reasoning
- direct drafting
- concise explanations
Meta Llama
| Field | Value |
|---|---|
| Username | @Llama_Meta_AI_bot |
| Provenance | Meta/Llama-style provider persona |
| Role | Open-Model Behavior Testing Construct |
| Utility | Open-model comparison, Llama-style output testing, and model-behavior contrast. |
| Routing Intent | Use for open-model behavior comparison and Llama-style response testing. |
| Capabilities | Model comparison, open-model framing, behavior contrast, response drafting. |
| Tools | Thinking note custom 82 tokens; Time 40 tokens; Http_fetch custom 90 tokens; Tags 21 tokens; Categories 29 tokens; Read 74 tokens; Researcher 539 tokens; Search 290 tokens; Search Meta Discourse 267 tokens |
| MCP server | Yes, get_full_toolkit |
| MCP Context Cost | ~963 tokens; 13 tools. |
| Total Tool Cost | ~2604 tokens ; 24 tools |
| Forced Tools | None |
| Default Model | DeepSeek, AI Tags only |
| Allowed Groups / Trust Level | Admins |
| Tags | llama, meta, open-model, model-comparison |
| Reference | # |
Explainer
Llama is the open-model comparison frame.
Use it to test or approximate open-model style behavior.
Ideal usecases:
- open-model behavior tests
- Llama-style drafting
- model comparison
- response contrast
- provider-family analysis
Venice Uncensored
| Field | Value |
|---|---|
| Username | Venice Uncensored • Venice |
| Provenance | Venice-style provider persona |
| Role | Venice Behavior and Provider-Comparison Construct |
| Utility | Venice-style persona testing, provider comparison, and model-behavior contrast. |
| Routing Intent | Use for Venice-aligned behavior testing, privacy/provider positioning, and provider comparison. |
| Capabilities | Provider comparison, Venice-style reasoning, behavior contrast, model-family testing. |
| Tools | Thinking note custom 82 tokens; Time 40 tokens; Http_fetch custom 90 tokens; Tags 21 tokens; Categories 29 tokens; Read 74 tokens; Researcher 539 tokens; Search 290 tokens; Search Meta Discourse 267 tokens |
| MCP server | Yes, get_full_toolkit |
| MCP Context Cost | ~963 tokens; 13 tools. |
| Total Tool Cost | ~2604 tokens ; 24 tools |
| Forced Tools | None |
| Default Model | DeepSeek, AI Tags only |
| Allowed Groups / Trust Level | Admins |
| Tags | venice, uncensored, provider-comparison, model-behavior |
| Reference | # |
Explainer
Venice Uncensored is the Venice-style provider frame.
Use it for Venice-specific positioning, model comparison, and behavior contrast.
Ideal usecases:
- Venice-style tests
- provider comparison
- privacy/provider positioning
- model-behavior contrast
- Venice-aligned drafting
Z.ai
| Field | Value |
|---|---|
| Username | @Z.ai_bot |
| Provenance | Z.ai / GLM-style provider persona |
| Role | Structured Reasoning and Provider-Comparison Construct |
| Utility | GLM-style reasoning tests, provider/model comparison, and structured answers. |
| Routing Intent | Use for structured answer generation, provider testing, and model-family comparison. |
| Capabilities | Structured reasoning, comparison, model-behavior testing, answer formatting. |
| Tools | Thinking note custom 82 tokens; Time 40 tokens; Http_fetch custom 90 tokens; Tags 21 tokens; Categories 29 tokens; Read 74 tokens; Researcher 539 tokens; Search 290 tokens; Search Meta Discourse 267 tokens |
| MCP server | Yes, get_full_toolkit |
| MCP Context Cost | ~963 tokens; 13 tools. |
| Total Tool Cost | ~2604 tokens ; 24 tools |
| Forced Tools | None |
| Default Model | DeepSeek, AI Tags only |
| Allowed Groups / Trust Level | Admins |
| Tags | z-ai, glm, structured-reasoning, provider-comparison |
| Reference | # |
Explainer
Z.ai is the GLM-style structured reasoning frame.
Use it for structured comparison and provider-family behavior testing.
Ideal usecases:
- structured answers
- GLM-style reasoning tests
- provider comparison
- model-family contrast
- formatted reasoning outputs